← 返回博客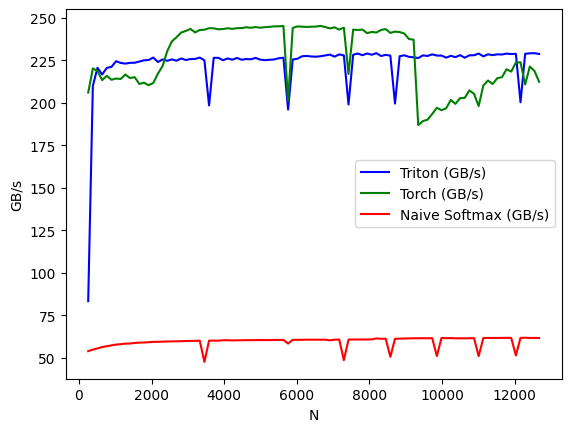
2026-07-29
在 Triton 里融合 Softmax
本周中段的第二个 kernel:融合 softmax。朴素 softmax 需要在内存上走三趟(求最大值、exp 加求和、做除法)——融成一趟后从约 55 GB/s 提到约 230 GB/s,快了 4 倍。
Triton 这条线在不同 block size 下也比 PyTorch 更紧、更稳定。
下一个:flash attention。
2026-07-29
本周中段的第二个 kernel:融合 softmax。朴素 softmax 需要在内存上走三趟(求最大值、exp 加求和、做除法)——融成一趟后从约 55 GB/s 提到约 230 GB/s,快了 4 倍。
Triton 这条线在不同 block size 下也比 PyTorch 更紧、更稳定。
下一个:flash attention。